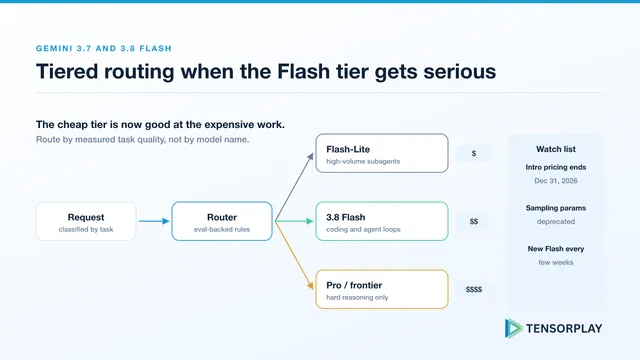
Gemini 3.7 and 3.8 Flash: When the Cheap Tier Gets Good at Coding
Gemini 3.7 and 3.8 Flash for production AI teams: benchmarks, pricing that doubles after December 2026, deprecated sampling parameters and tiered routing.
3 articles
Gemini 3.7 and 3.8 Flash for production AI teams: benchmarks, pricing that doubles after December 2026, deprecated sampling parameters and tiered routing.
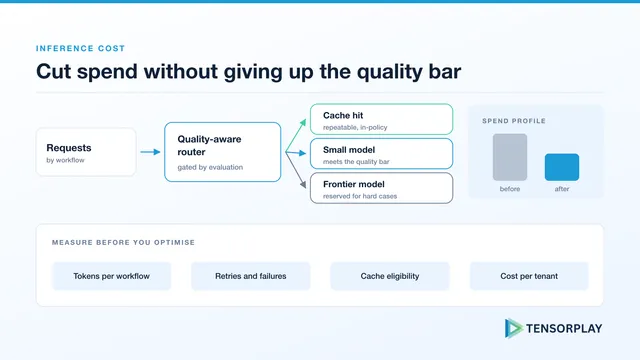
A playbook for reducing LLM inference costs: per-workflow cost profiling, quality-aware routing, semantic caching, prompt compression and infrastructure.
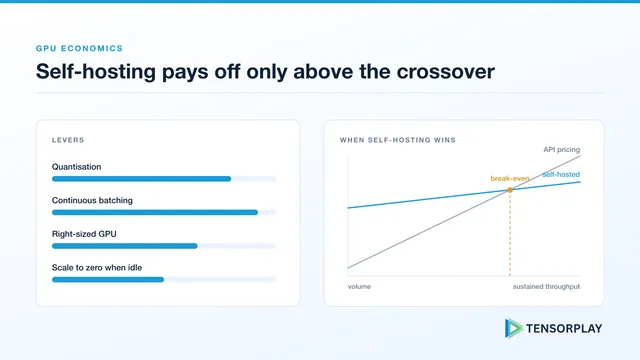
Optimize the cost of self-hosted GPU inference with practical guidance on model serving, utilization, batching, and infrastructure choices.